Problem
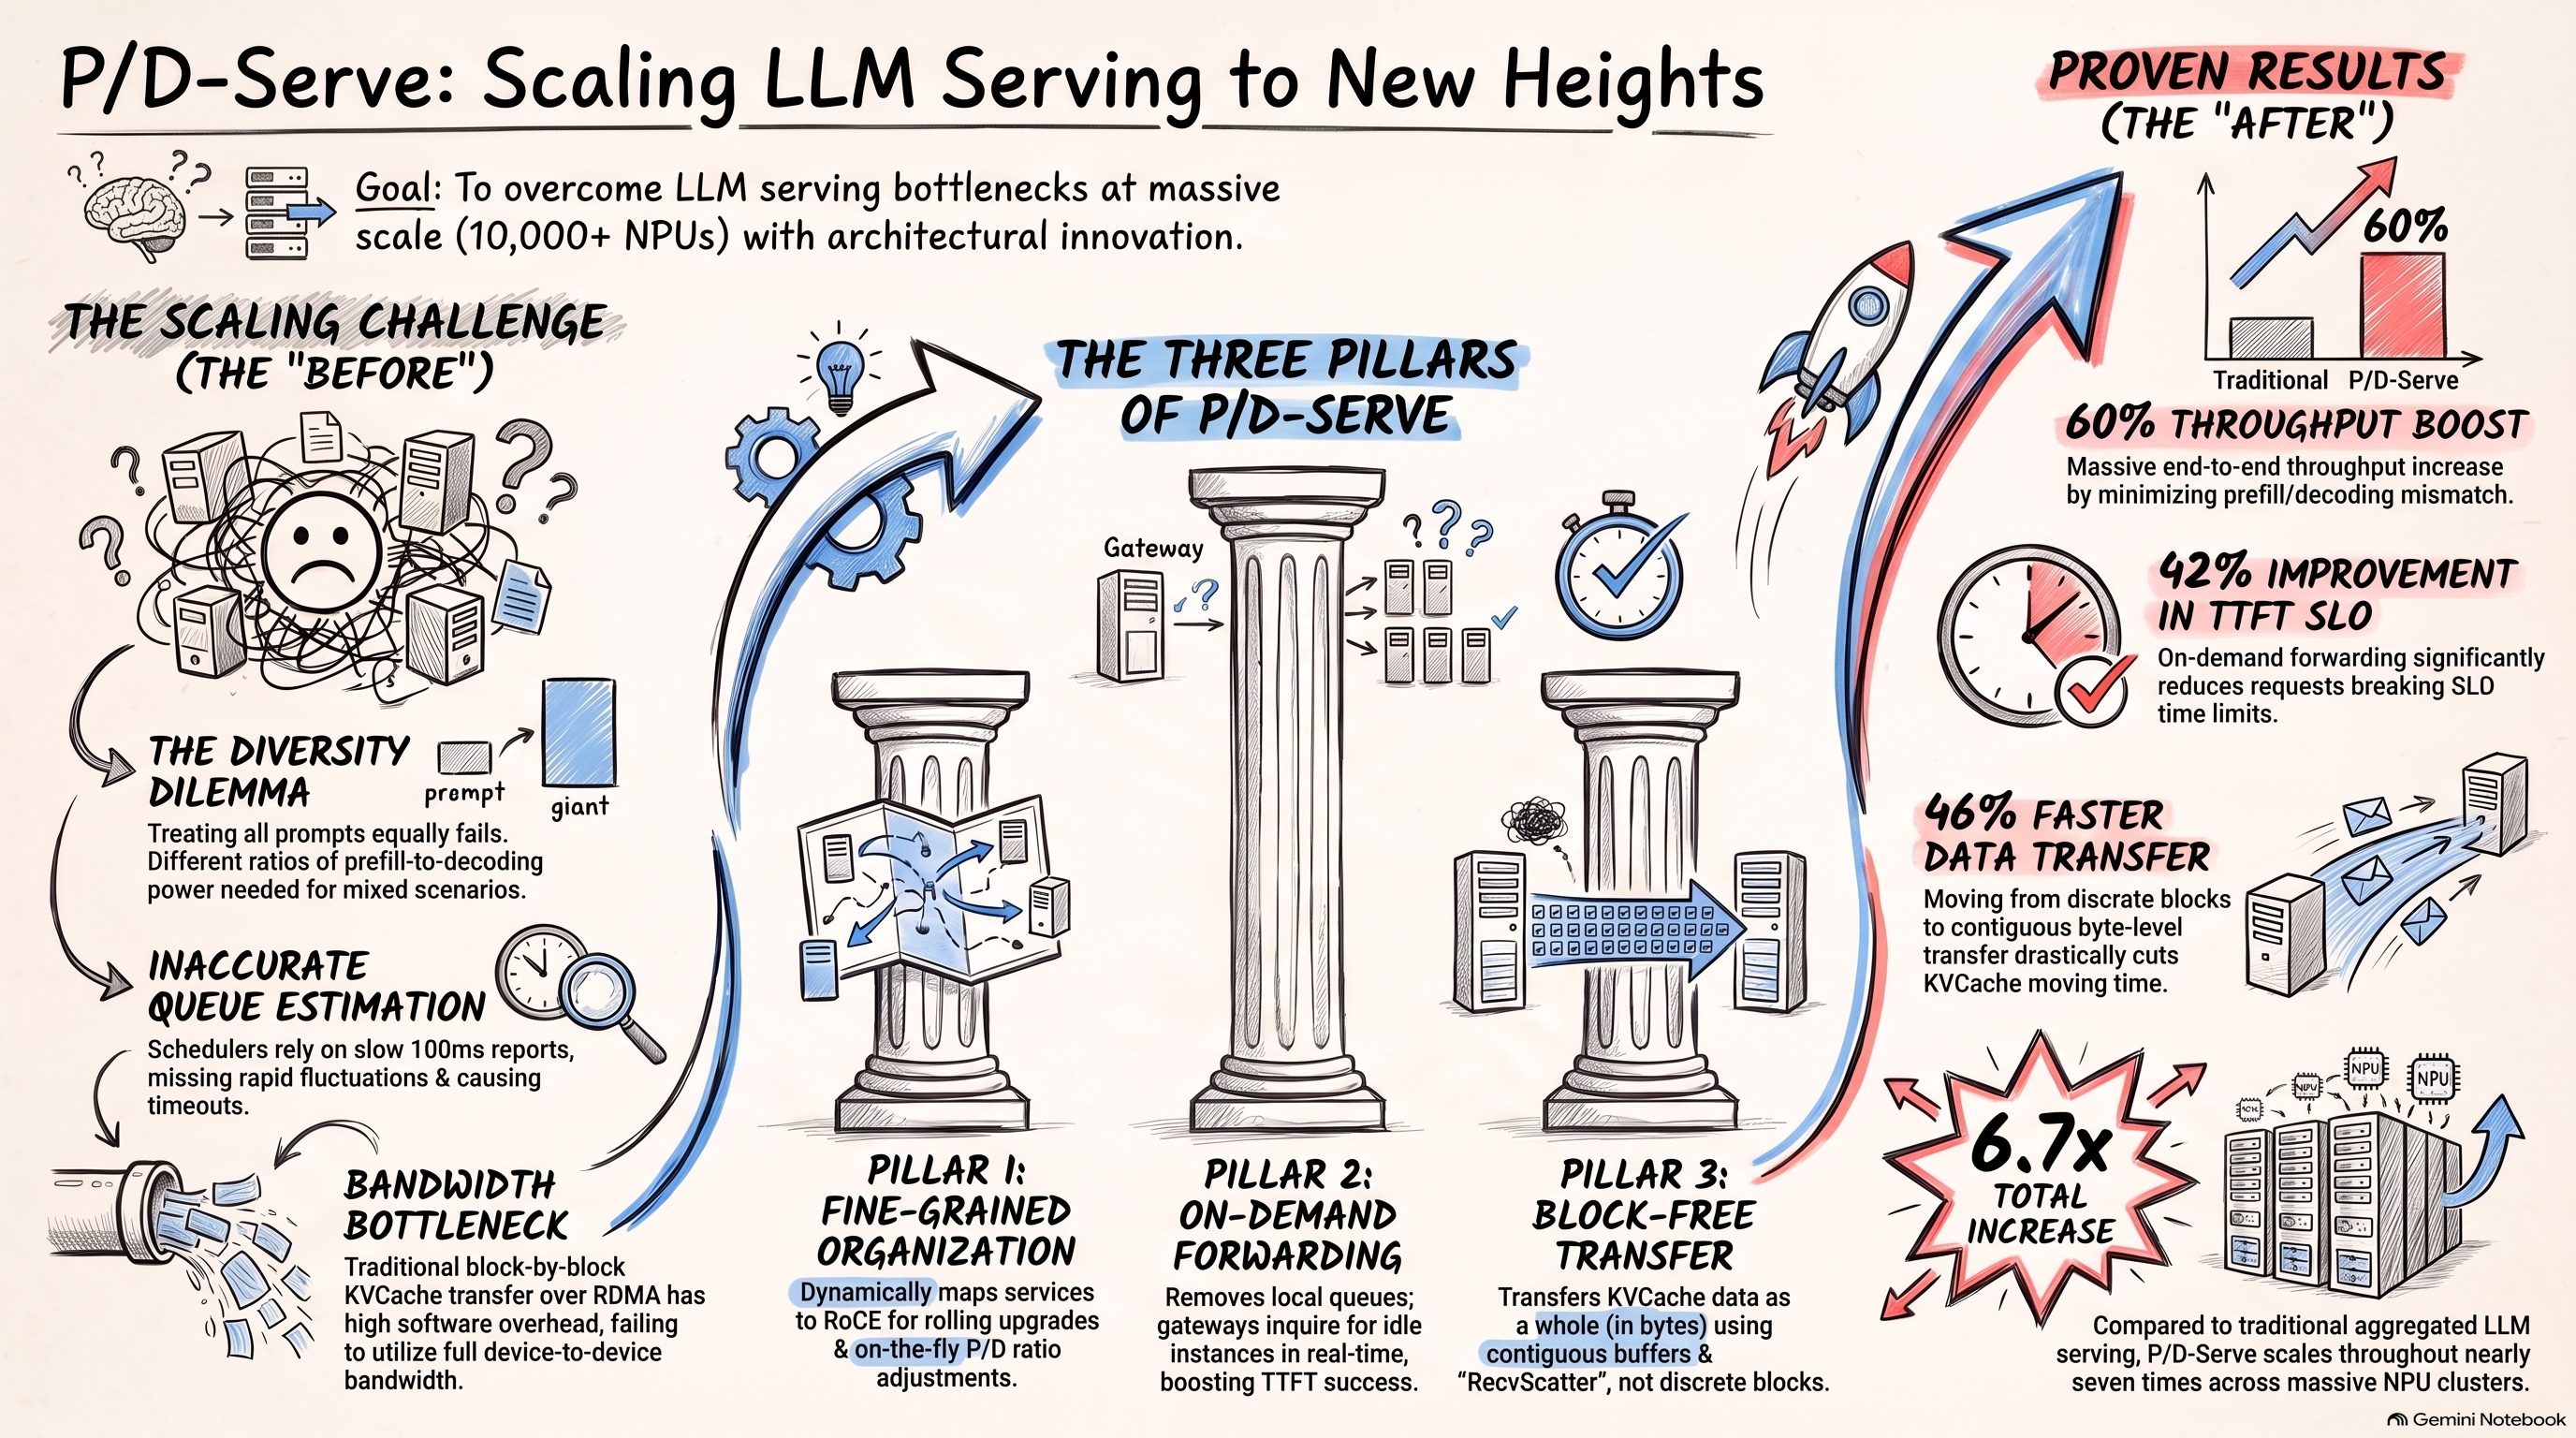
Serving disaggregated LLMs across tens of thousands of accelerators requires fine-grained organization of prefill and decoding workloads with dynamic P/D ratio adjustment. Inaccurate global workload estimates cause prefill timeouts, and device-to-device KVCache transfer over cluster-level RDMA stays underutilized.
Approach
P/D-Serve is an end-to-end system covering fine-grained P/D mapping over RoCE networks, on-demand forwarding that avoids prefill timeouts under workload-estimate error, and optimized D2D KVCache transfer. It is built on Ascend hardware and MindSpore.
Public evidence
The public abstract states that P/D-Serve has been deployed over tens of thousands of NPUs in commercial use for more than eight months, and reports further improvements of 60% in end-to-end throughput, 42% on the time-to-first-token SLO metric, and 46% in D2D transfer time. The abstract does not name the comparison baseline for these three figures. A 6.7x throughput increase is reported for the optimized end-to-end system compared with aggregated LLM serving; whether that comparison is a production or testbed measurement is not stated. Treat all figures as operator-reported under the conditions above.
Takeaway
The work treats disaggregation as a cluster-level scheduling and transfer problem, complementing the site's line on reliable serving under changing load and hardware conditions.
Bibliographic details
- Authors
- Yibo Jin, Tao Wang, Huimin Lin, Mingyang Song, Peiyang Li, Yipeng Ma, Yicheng Shan, Zhengfan Yuan, Cailong Li, Yajing Sun, Tiandeng Wu, Xing Chu, Ruizhi Huan, Li Ma, Xiao You, Wenting Zhou, Yunpeng Ye, Wen Liu, Xiangkun Xu, Yongsheng Zhang, Tiantian Dong, Jiawei Zhu, Zhe Wang, Xijian Ju, Jianxun Song, Haoliang Cheng, Xiaojing Li, Jiandong Ding, Hefei Guo, Zhengyong Zhang
- Venue
- arXiv 2024
- Status
- Preprint